Semantic Segmentation vs Object Detection: Understanding the Differences

Computer vision can help AI both recognize objects in images and determine their location, shape, and boundaries. For this, different approaches are used, in particular semantic segmentation and object detection. The choice depends on what information the model needs to obtain and how precisely objects must be outlined.
Quick Take
- Object detection finds objects and marks them with bounding boxes.
- Semantic segmentation determines the class of every pixel, forming more precise boundaries of objects and regions.
- Detection is suitable for finding and counting objects, while segmentation is for analyzing their shape and area.
- Both approaches can be combined if the task requires both object localization and detailed image analysis.
- The quality of the result depends not only on the algorithm, but also on the accuracy of the training data annotation.
What is Object Detection?
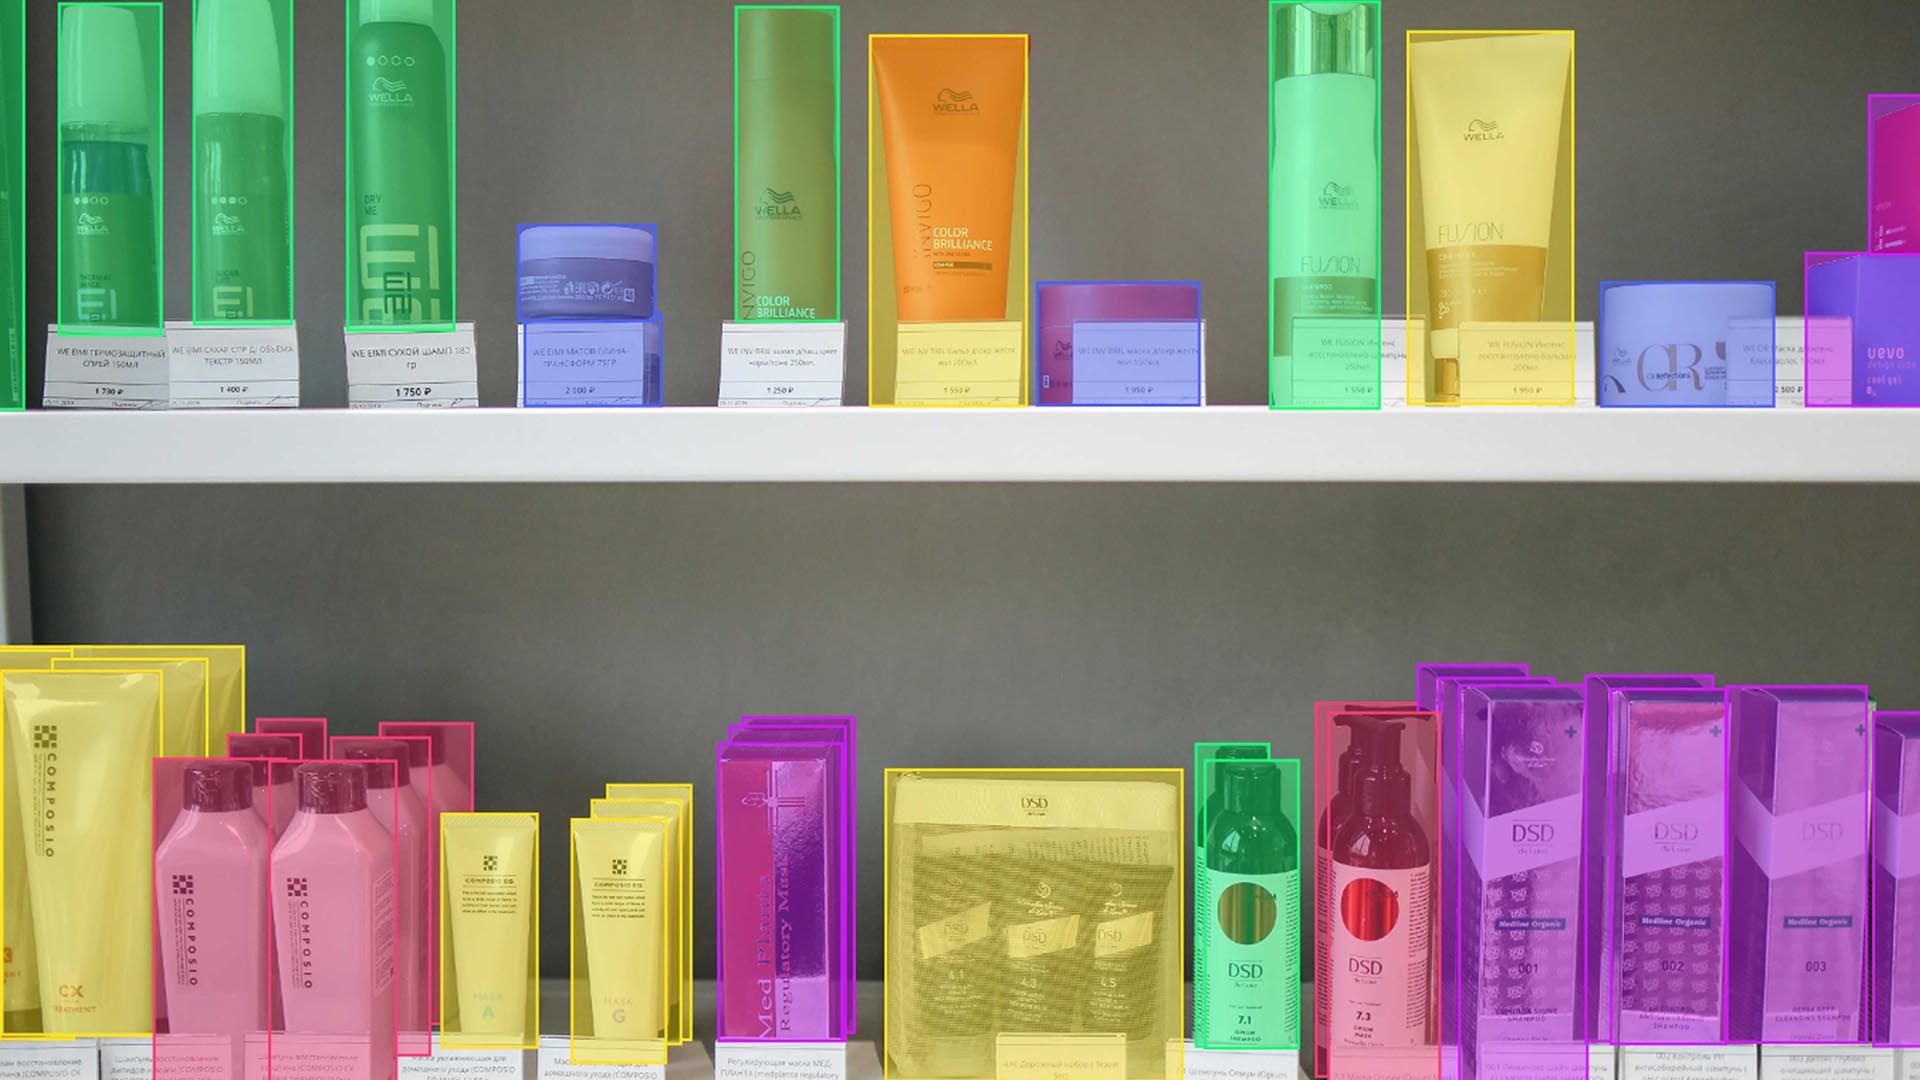
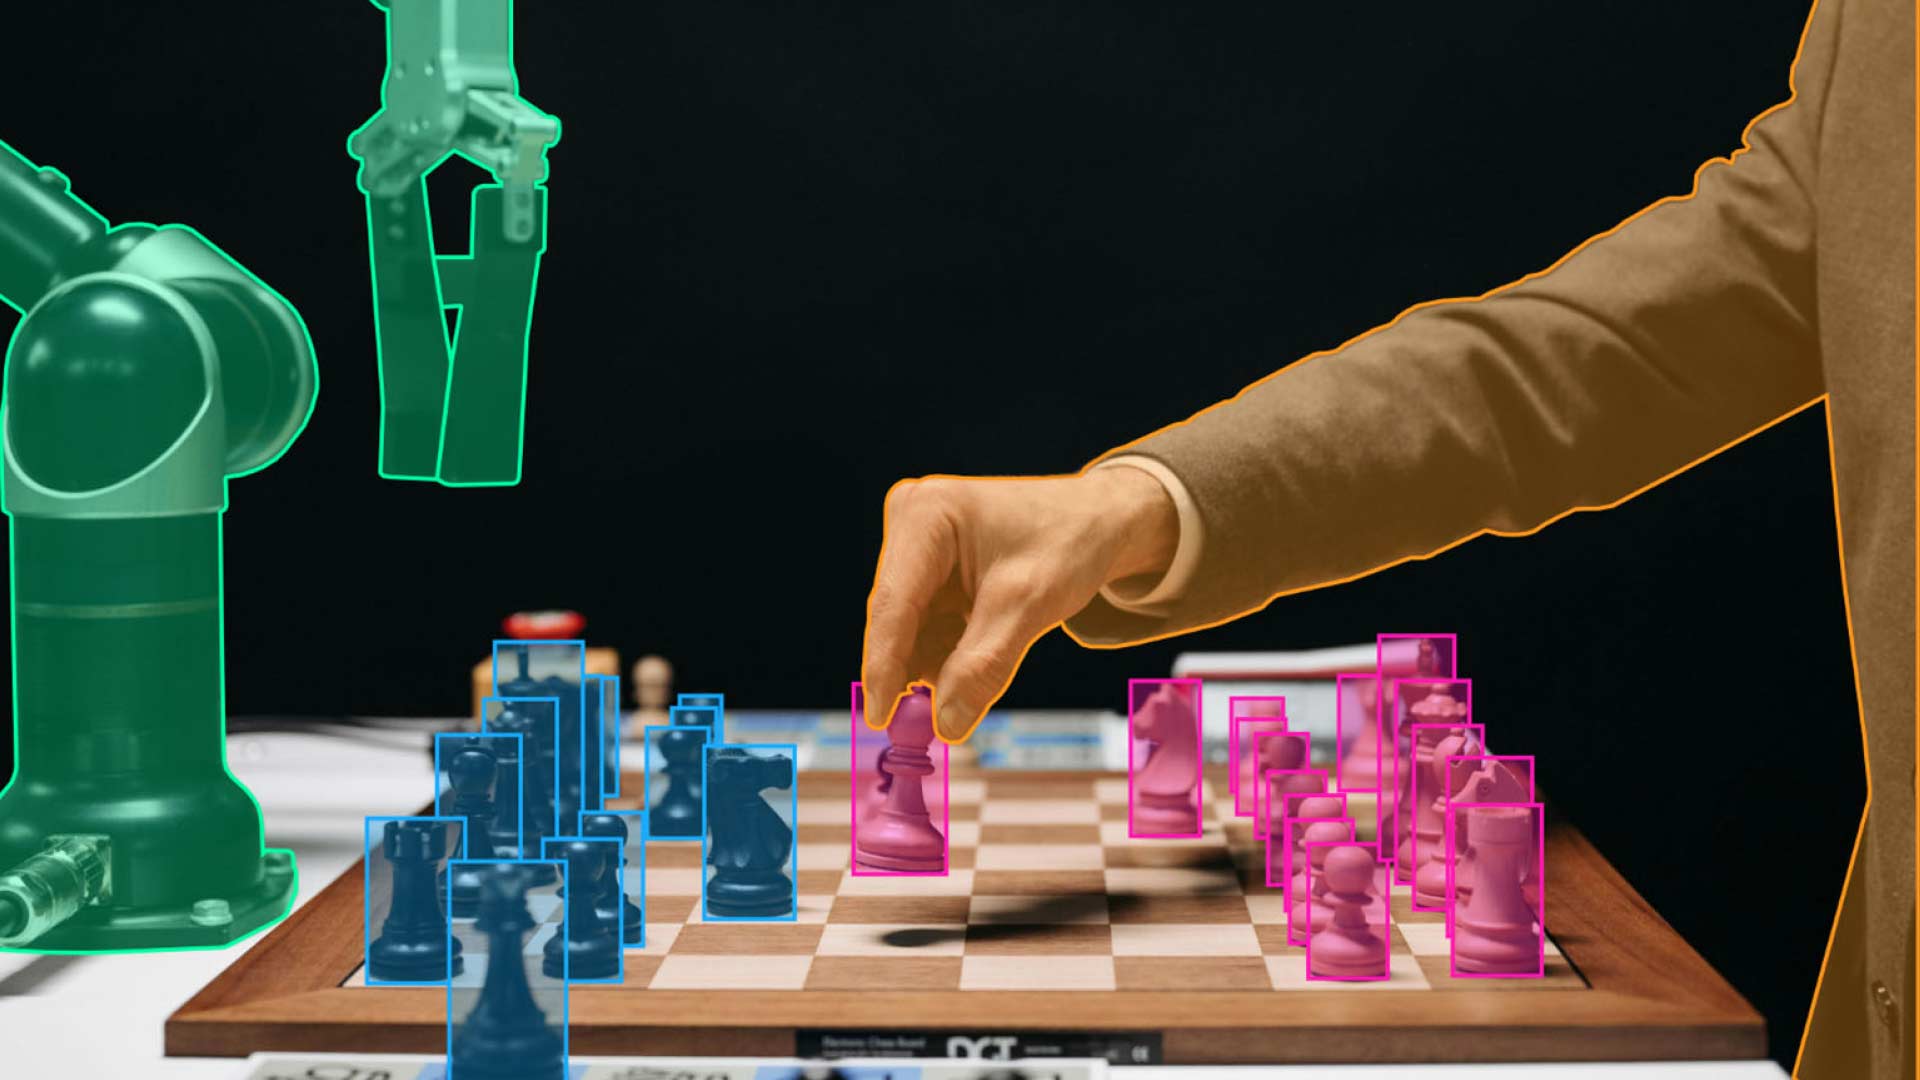
Object detection is a computer vision method that determines which objects are present in an image and exactly where they are located. The result is typically represented by bounding boxes with a class name for each found object.
This approach is useful when you need to quickly find objects, count them, or track their appearance in video. It is used in autonomous transport, video surveillance, agriculture, and retail.
Among well-known architectures is YOLO, which is widely used for rapid object detection. The specific choice of model depends on speed, accuracy, and operational requirements.
What is Semantic Segmentation?
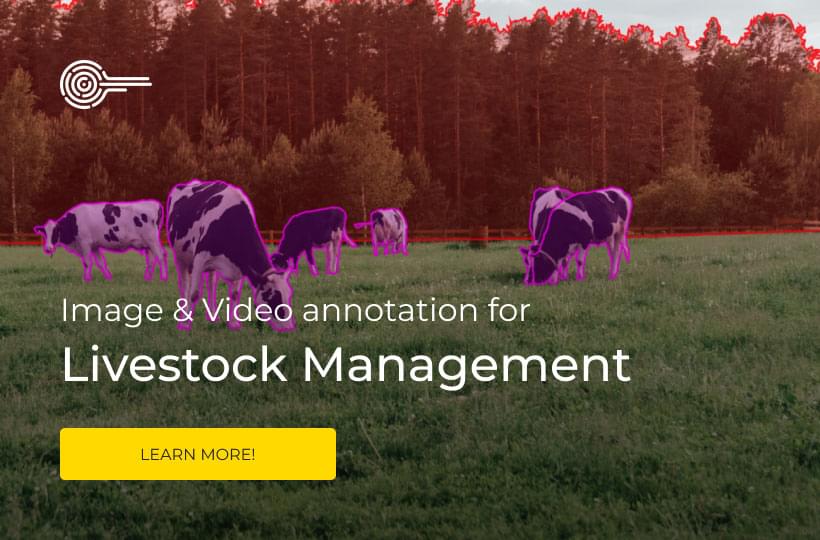
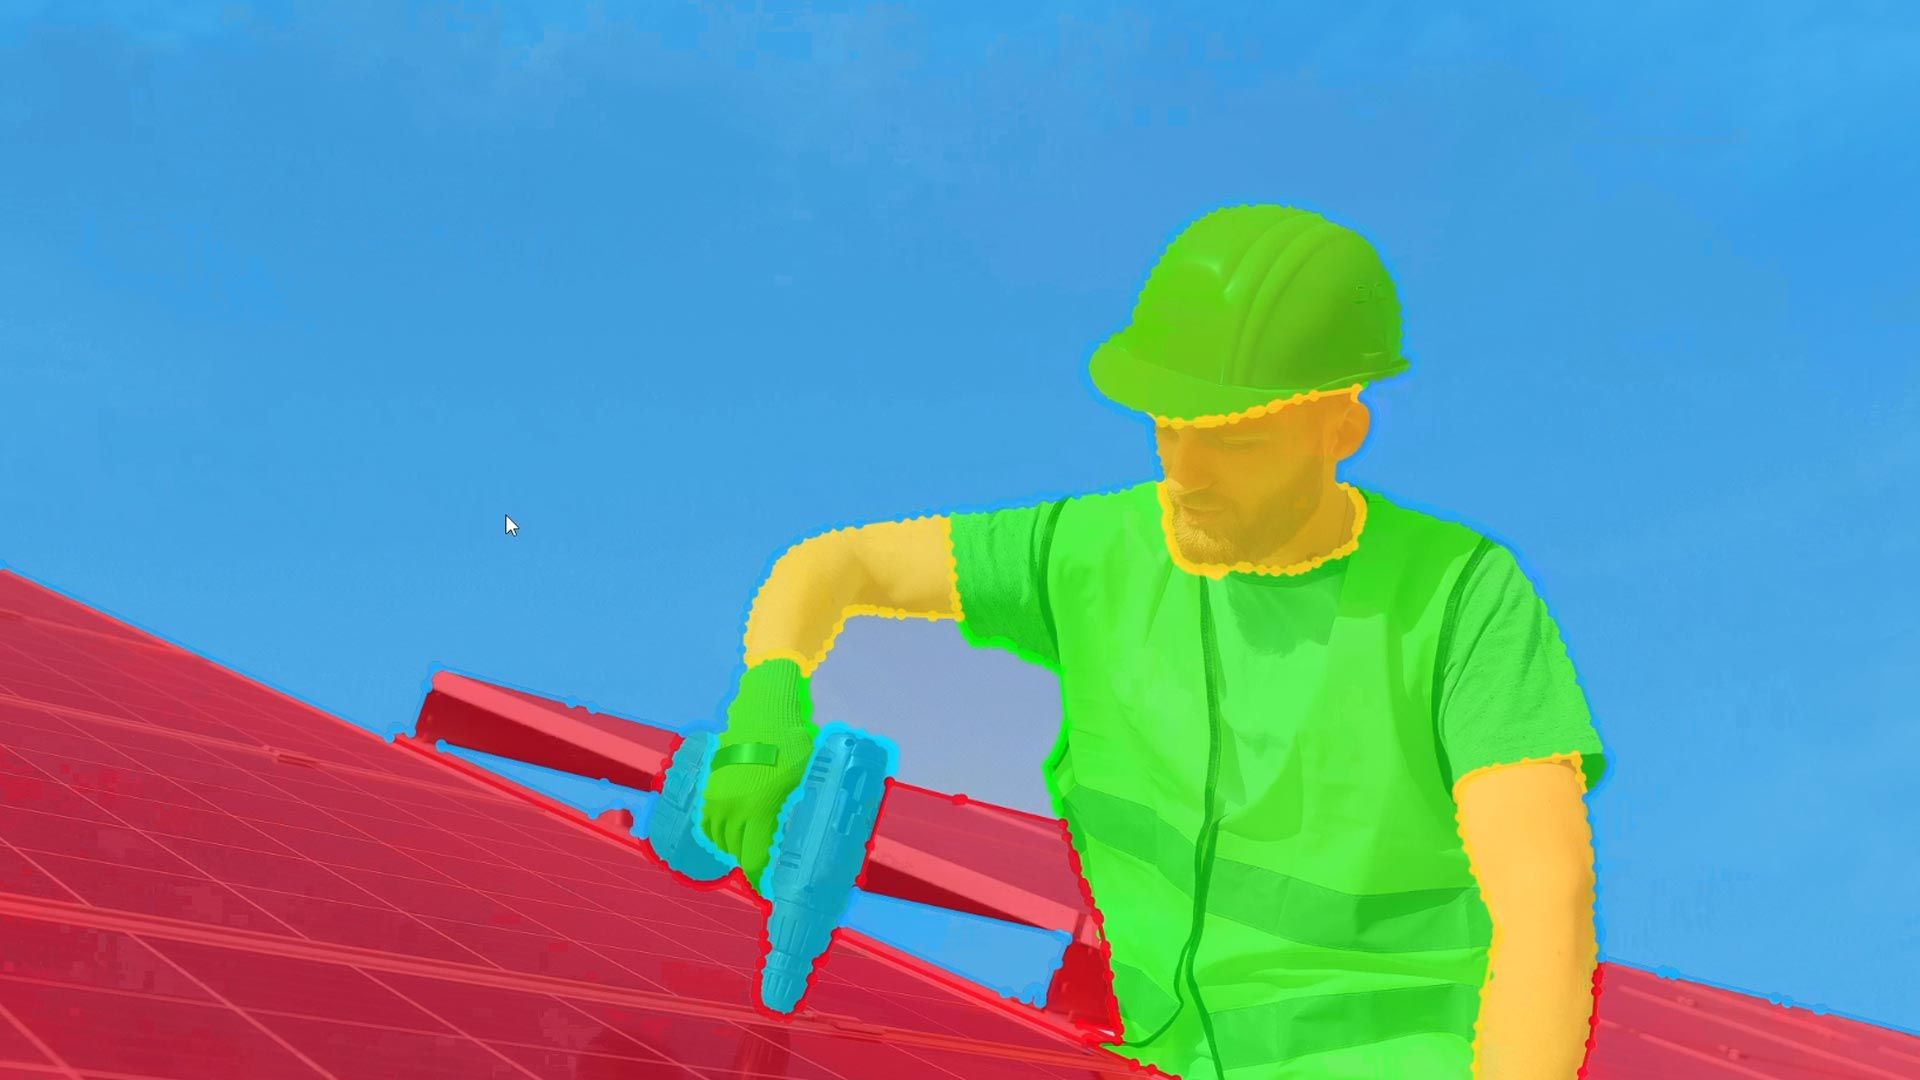
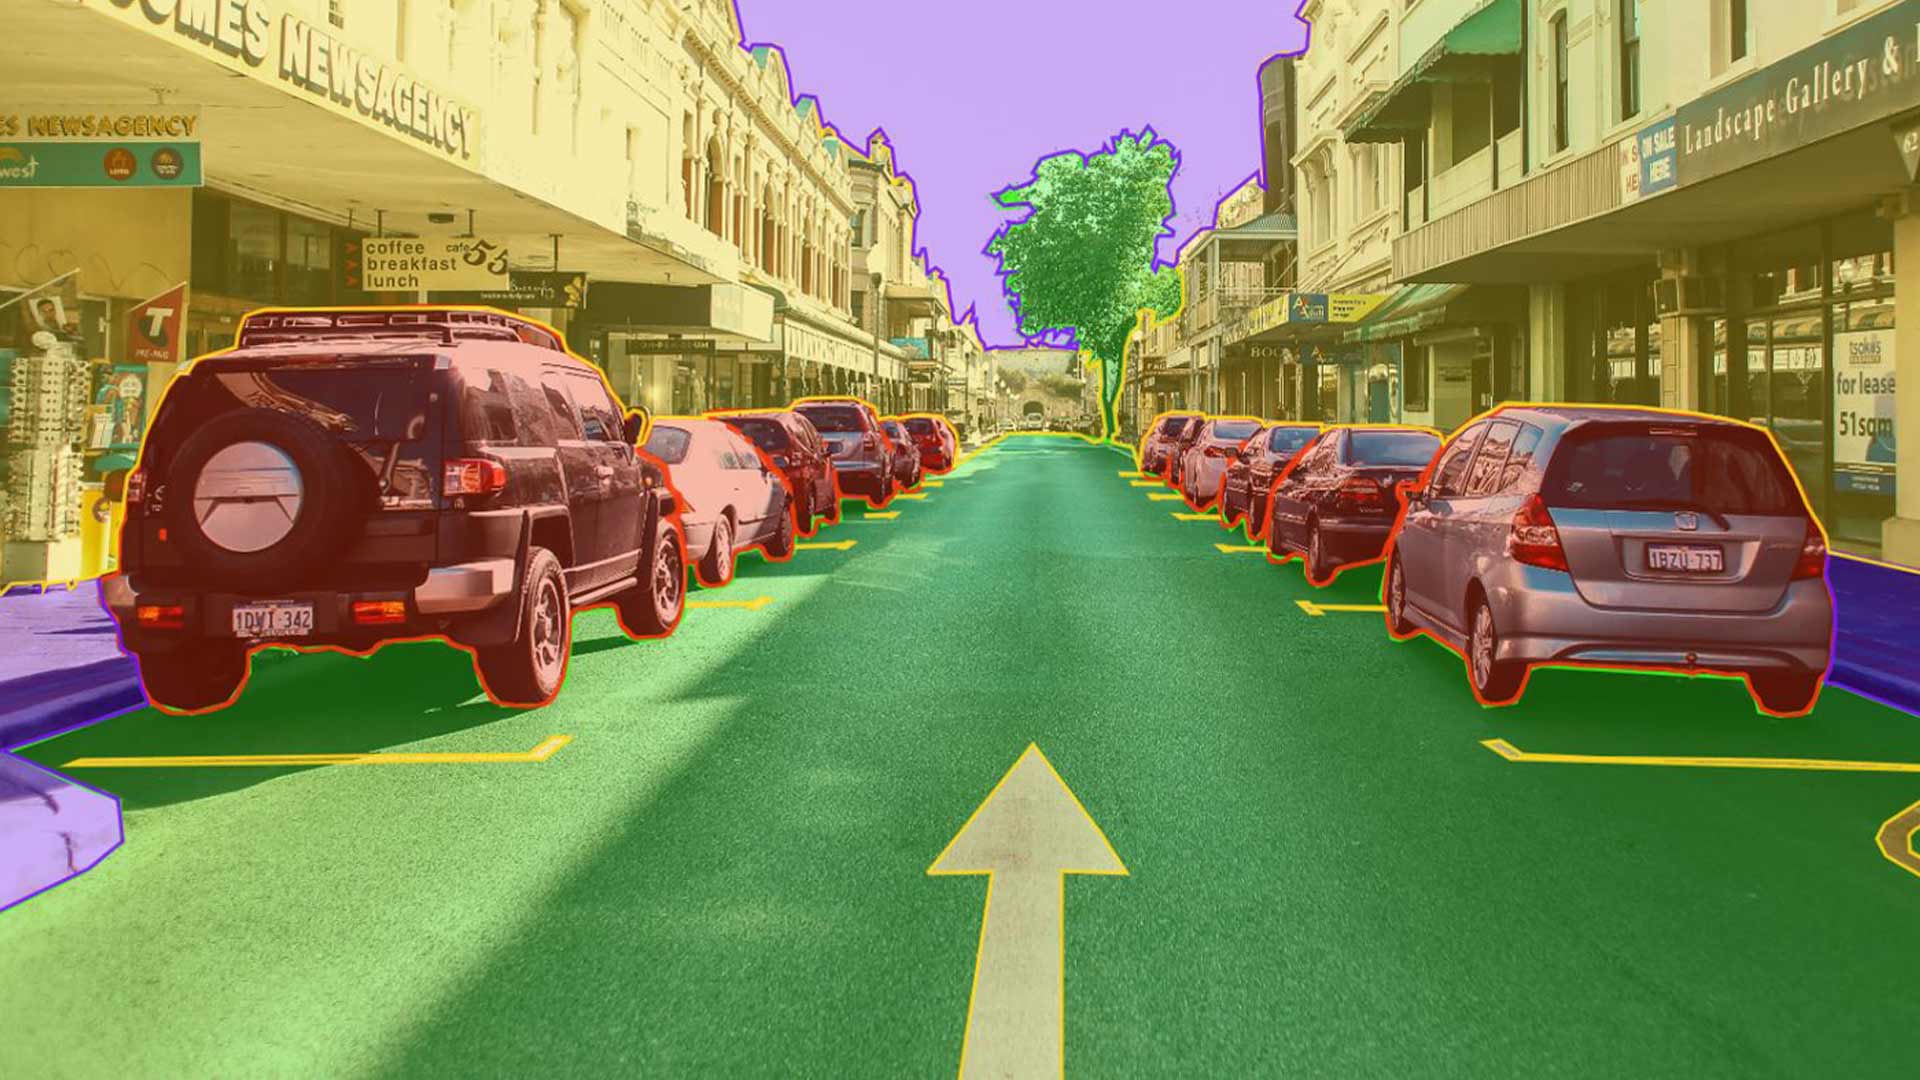
Semantic segmentation is a method that assigns a class to every pixel of an image. Instead of bounding boxes, the model creates a mask showing which specific areas belong to a given category.
Thanks to this, it is possible to more precisely determine the shape of objects, the boundaries between different regions, and the area they occupy. Usually, this approach is applied for medical image analysis, manufacturing defect detection, cartography, and robot navigation.
One important characteristic to consider: semantic segmentation does not distinguish between individual objects of the same class. If there are five cars in an image, the model may mark them all as a single category "car" without assigning a separate identifier to each.
Main Limitations and "Pitfalls" of the Methods
No computer vision approach guarantees a hundred-percent error-free result. Ignoring the weak points of a model during the planning phase can cost time, budget, and the accuracy of the entire project. Let us examine the difficulties developers encounter when working with each method.
Limitations of Object Detection
- The "Excess Background" Problem. A bounding box never repeats the contour of an object perfectly. Along with the item itself, the box captures part of the background or neighboring elements. Because of this, the method is entirely unsuitable for tasks requiring microscopic measurements or precise area analysis.
- Object Occlusion and Crowding. If objects partially overlap one another or are located very close together in a dense cluster, bounding boxes can merge, overlap, or become "lost".
- Unusual or Deformed Shapes. If an item is tilted at an odd angle, or has an unusual oblong or curved shape, a bounding box gives a false impression of its true dimensions.
Limitations of Semantic Segmentation
- Sensitivity to Quality and Transitions. The model can make serious errors on blurred contours, fine details, transparent surfaces, or frames with low lighting and quality. It is difficult for AI to establish a clear boundary where even the human eye cannot distinguish one.
- Colossal Annotation Costs. While drawing a bounding box around a car takes an annotator a few seconds, creating an ideal pixel mask for a complex object requires tens of times more time and manual labor. This makes datasets for segmentation substantially more expensive.
- Computational Heaviness. Due to the massive amount of data to process (analyzing every pixel), segmentation models demand powerful GPUs and are less frequently suited for lightweight mobile apps or Edge AI devices operating in real time.
How to Determine Which Annotation Type Is Needed
The main difference between the approaches is the level of detail in the result. Imagine a manufacturing quality control system. If you need to find damaged parts on a conveyor belt, object detection can determine their location. If you need to measure the area of a scratch or precisely outline a defect, semantic segmentation will provide more useful information.
The annotation type should be chosen before preparing the training dataset. Label format, time expenditure, validation requirements, and the capabilities of the future model all depend on it.
For object detection, annotators mark each object with a bounding box and assign it a class. For semantic segmentation, they determine which pixels belong to each category. It is important to agree upon rules in advance for complex cases: partially hidden objects, indistinct boundaries, and situations where multiple categories are visually similar. Without unified criteria, different annotators may mark identical images differently, complicating model training.
Can Segmentation and Detection Be Combined?
In some projects, a single method is indeed insufficient, so teams combine multiple computer vision tasks. In advanced computer vision applications, combining methods has proven to be a powerful approach. By merging the outputs of these approaches, machines can leverage the strengths of each to achieve higher accuracy and gain a deeper understanding.
For instance, in the context of autonomous driving, combining segmentation, detection, and classification plays a decisive role in ensuring safe navigation and intelligent decision-making. Segmentation algorithms can identify drivable areas and other road objects, while object detection methods can precisely pinpoint specific objects such as pedestrians and vehicles. Classification then assigns appropriate labels for further understanding and interpretation of the environment.
This combined approach enables autonomous vehicles to maintain a holistic view of the surrounding world, leading to more accurate object detection and classification, as well as better contextual understanding.
However, a combined system significantly increases demands on data, computation, and testing. Therefore, you should first determine what exact information needs to be obtained, and only then select the architecture.
FAQ
What is the difference between semantic segmentation and instance segmentation?
Semantic segmentation assigns a class to every pixel, but does not distinguish between individual objects of the same class. Instance segmentation creates a separate mask for each individual object, making it useful when the system needs to count or track distinct elements.
Which types of images are difficult for segmentation models to process?
Images with low contrast, poor lighting, motion blur, object occlusion, or indistinct boundaries can be challenging. Transparent materials, thin structures, and very small objects can also reduce segmentation accuracy. Representative training data and consistent annotation rules help resolve these difficulties.
How can teams reduce the cost of semantic segmentation annotation?
Teams can use pre-trained models to generate initial masks, allowing annotators to review and correct them rather than drawing every mask from scratch. Prioritizing complex examples, utilizing consistent annotation rules, and implementing quality audits can also reduce rework. However, automated masks still require verification, especially in high-cost applications.
How do teams decide whether to combine object detection and segmentation?
Combining both methods makes sense when a project requires both locating individual objects and understanding their precise boundaries or surrounding areas. For example, a robotic system might use detection to locate a tool and segmentation to determine its contour. If a task requires only object localization, combining methods may add unnecessary complexity and cost.