Advanced AI Model Training Techniques Explained
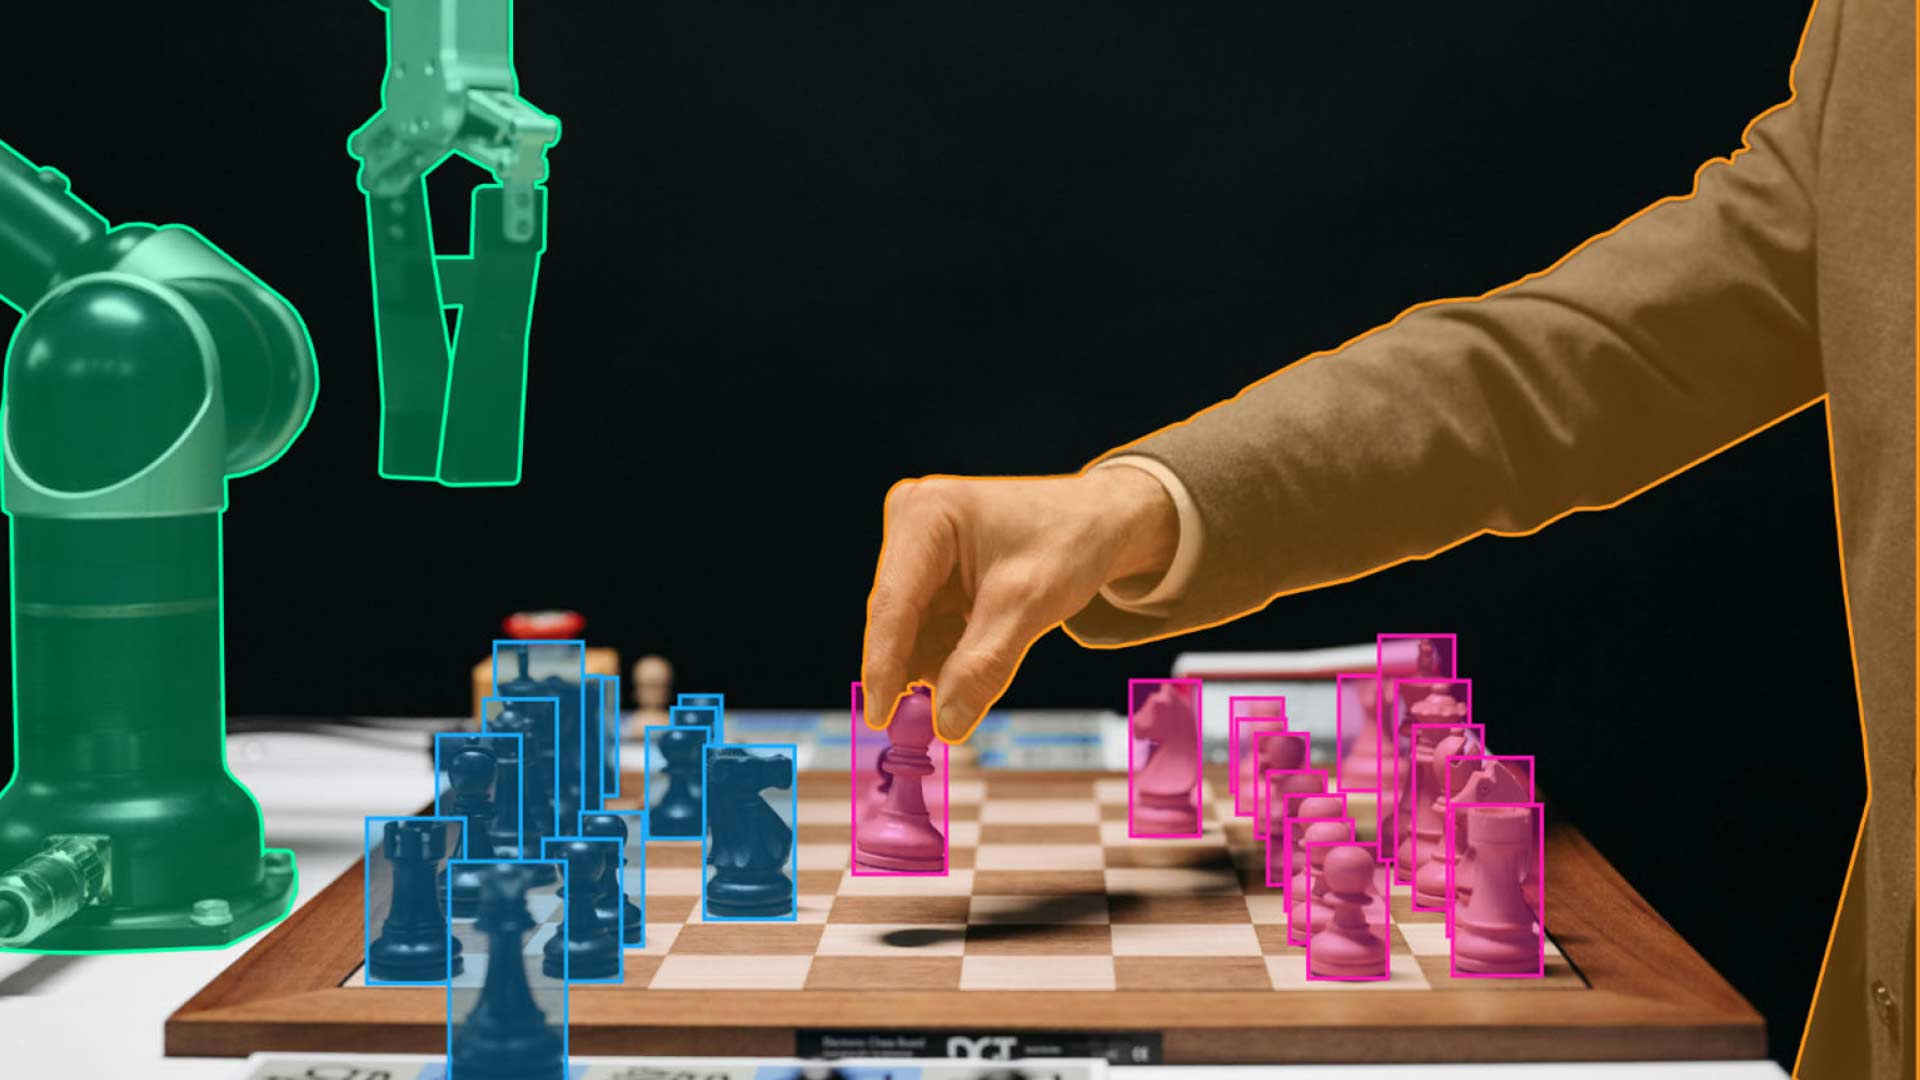
Creating a working AI model is a sequential process where every step determines whether the system can operate in real life. So, let us examine how artificial intelligence training is structured, what methods exist, and where errors most frequently occur that ruin the accuracy of even well-thought-out systems.
Quick Take
- Training an AI model helps it identify patterns in data and execute specific tasks.
- Supervised learning, self-supervised learning, transfer learning, and fine-tuning differ in operating principles, data requirements, and resource needs.
- The optimal method depends on the task, available data, budget, and expected quality of results.
- Poor-quality annotation, data leakage, inappropriate metrics, and overfitting can reduce model accuracy.
- To prevent quality from degrading over time, the model must be continuously monitored and retrained.
Core Methods of Training AI Models
During training, a model processes examples, calculates error, and adjusts its parameters according to the chosen optimization algorithm. Afterward, it is tested on data that was not used for direct training. This helps determine whether the model has learned useful patterns or merely memorized familiar examples.
The choice of method depends on the task type, available data, computational budget, and requirement specifications for the result. The most common approaches solve different problems and are not always interchangeable.
How to Choose the Best Approach to Training?
Everything starts with clear requirements. You need to immediately determine: what constitutes success, how critical errors are, what data is "at hand", and where exactly the final product will operate.
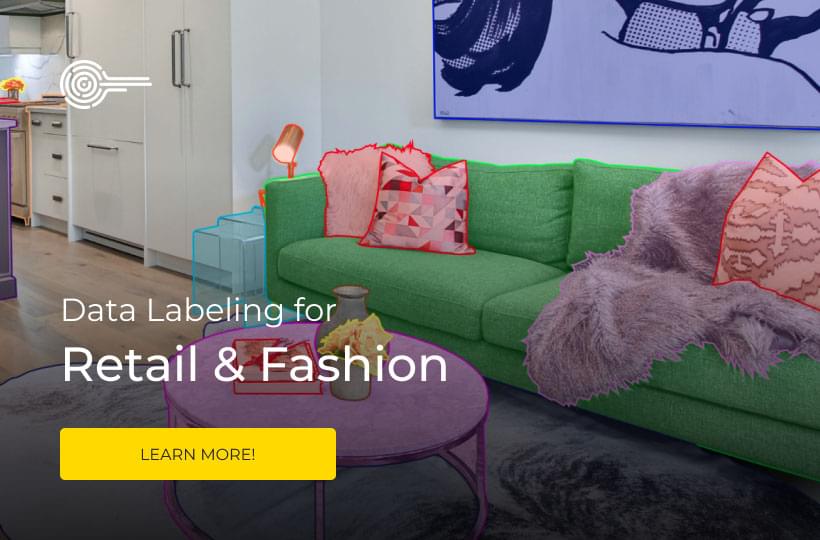
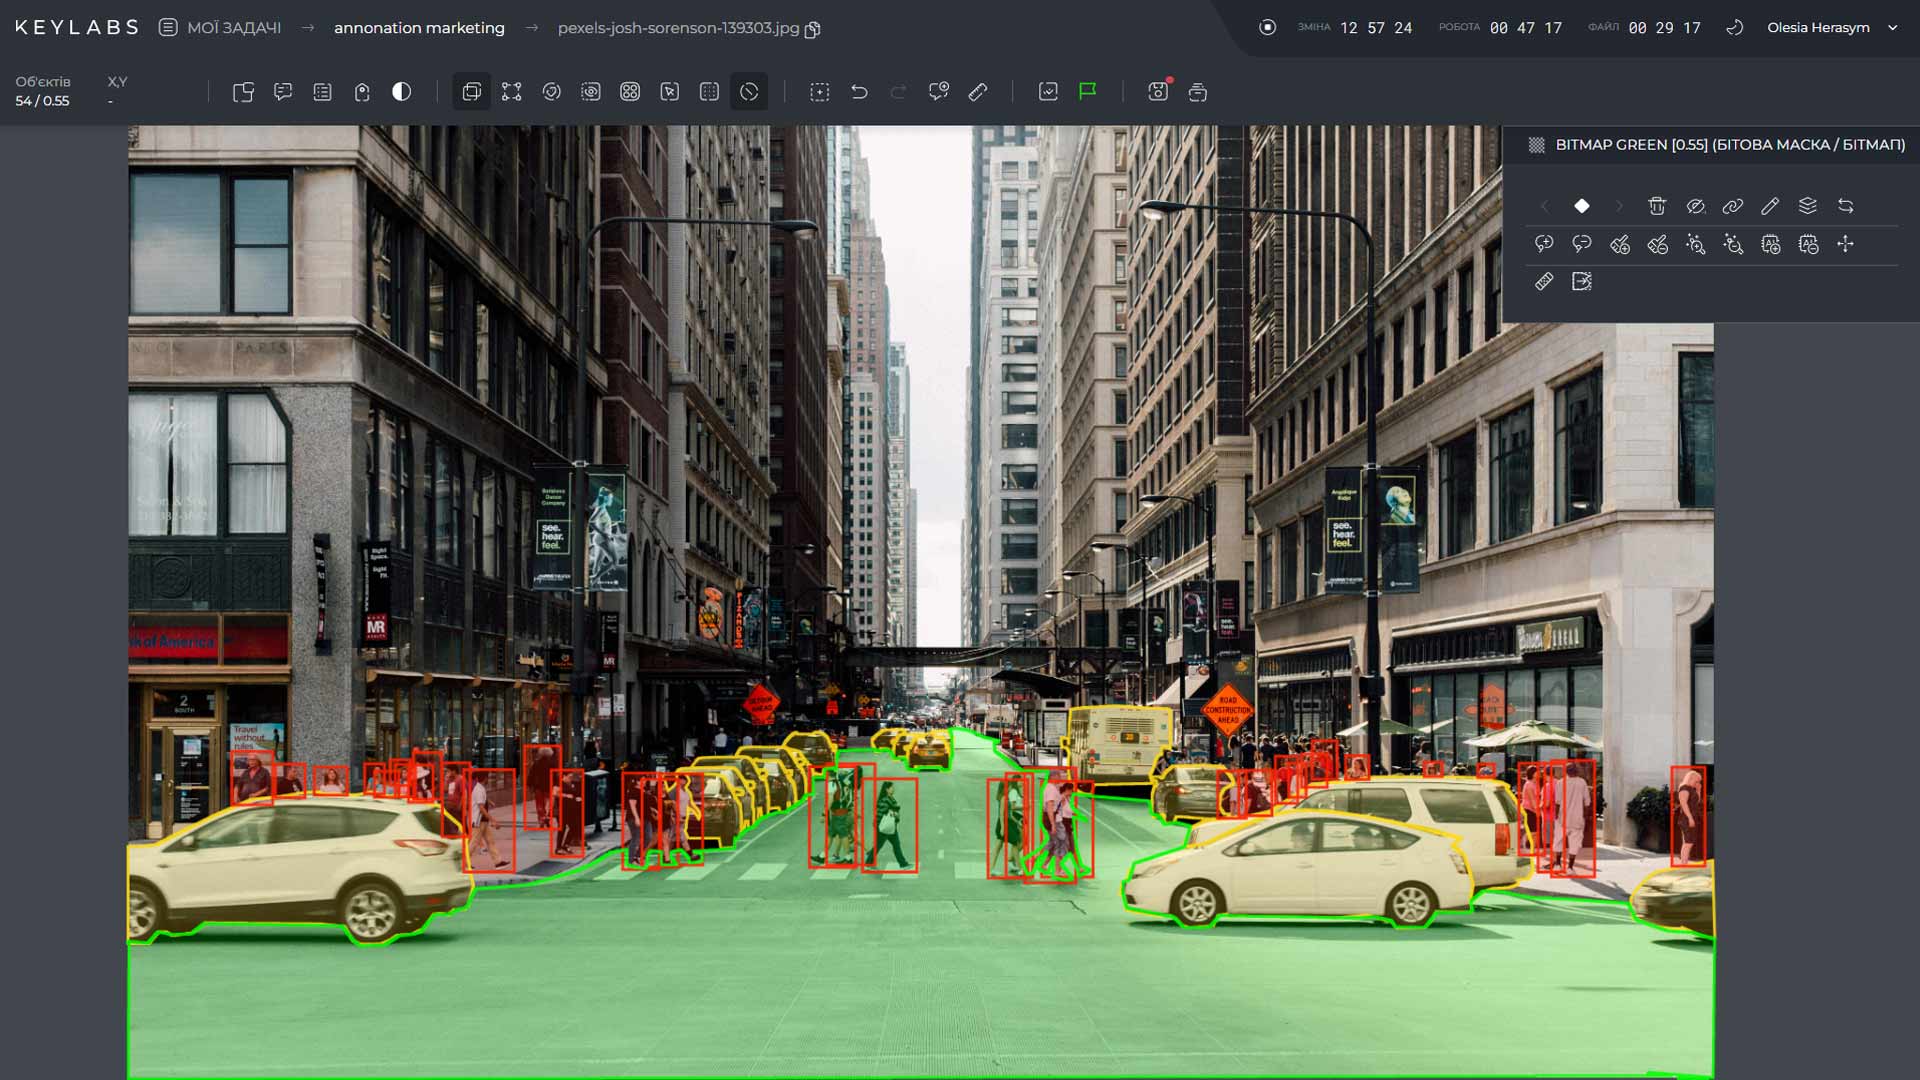
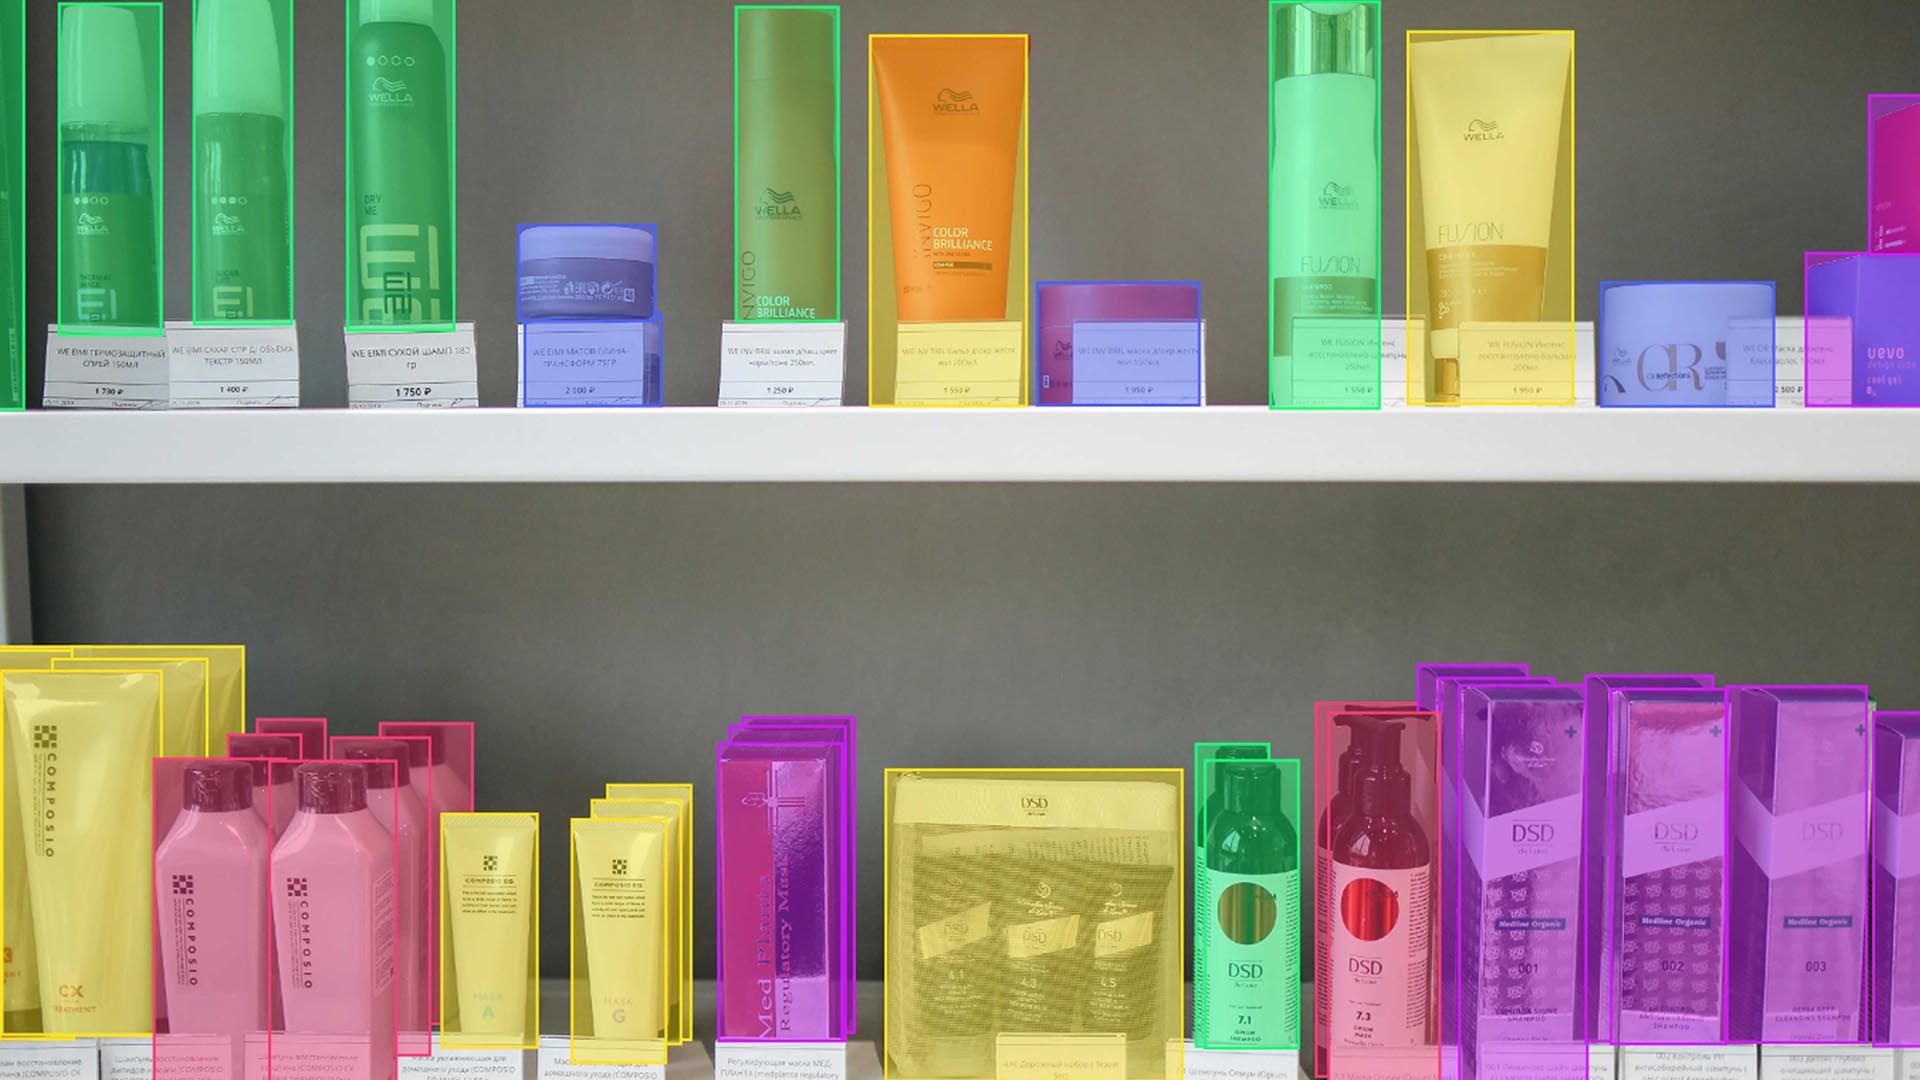
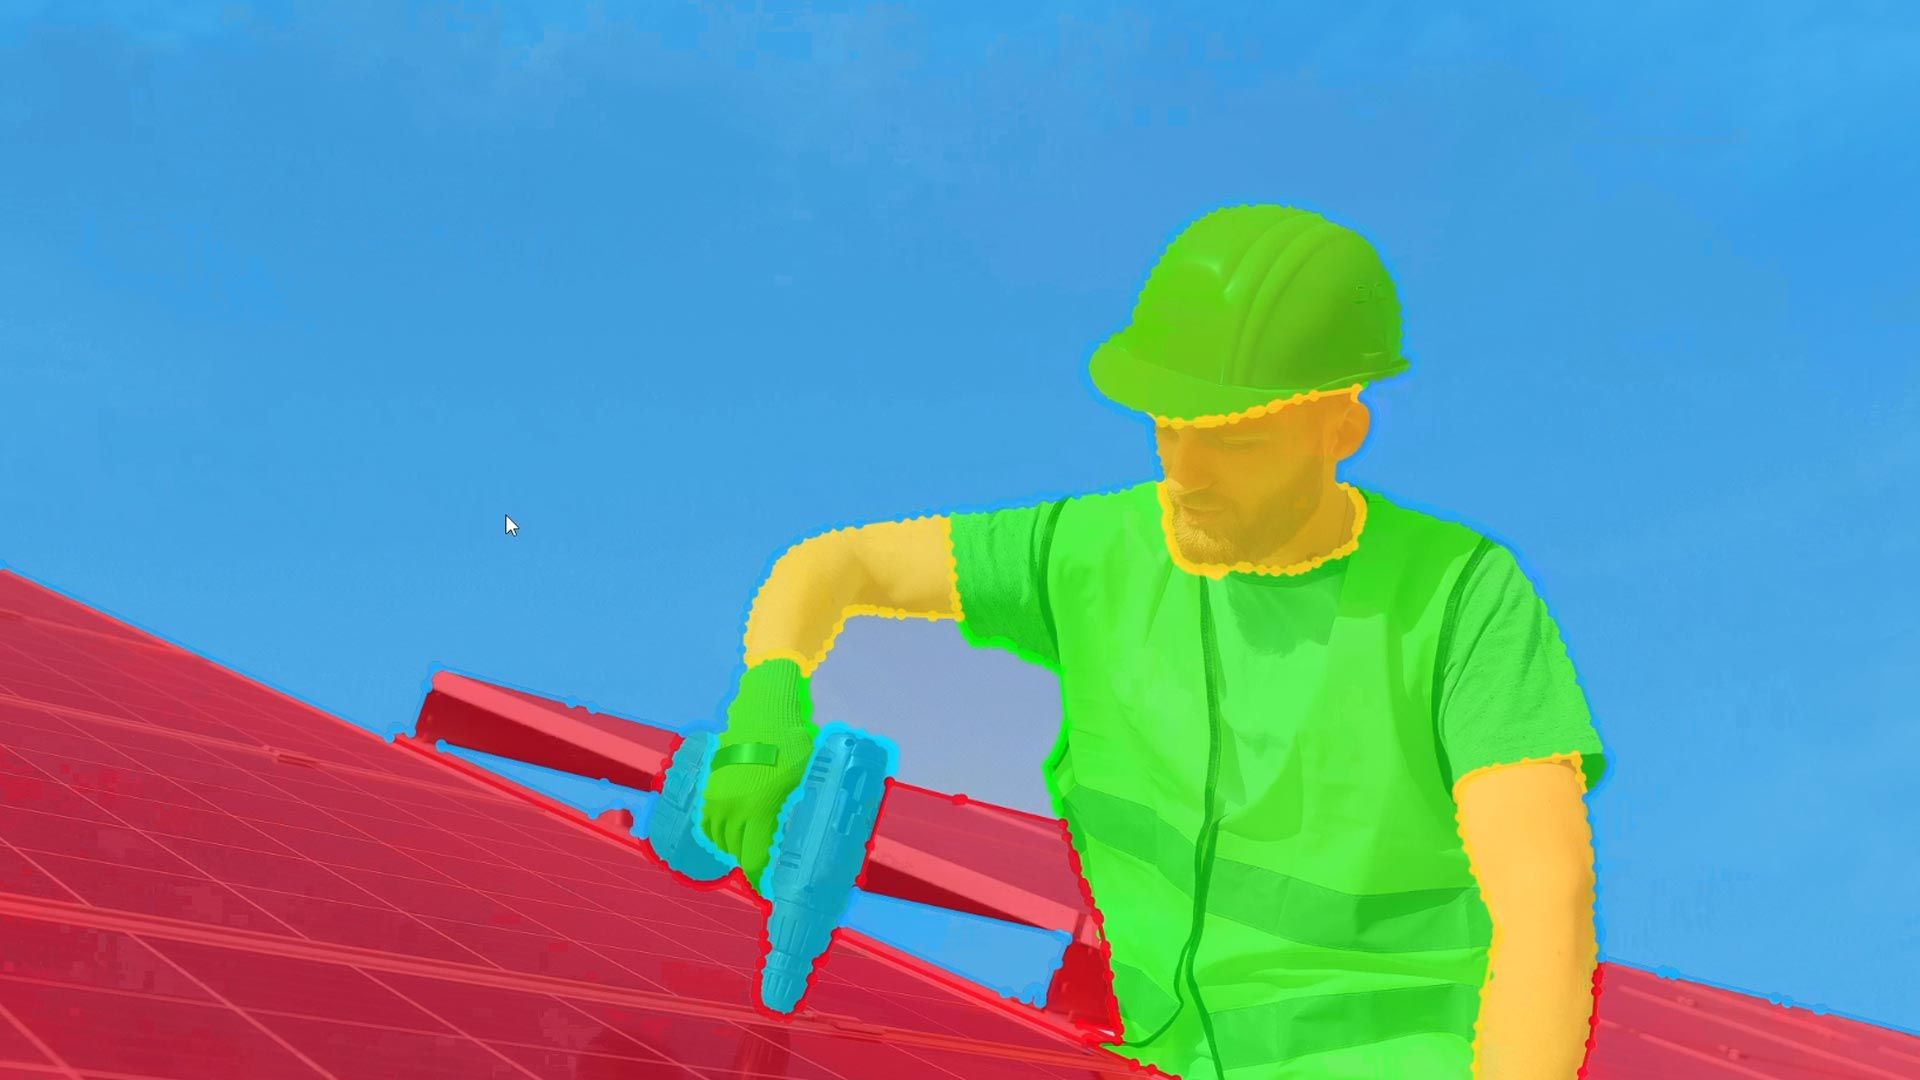
Have lots of labeled data? If you are building a factory defect detection system and have thousands of labeled photos – feel free to choose supervised learning.
Need to adapt a language model for a narrow niche? If you need to teach an AI legal terminology or corporate style – look toward fine-tuning.
Is data constantly changing? If the AI has to answer questions based on documentation updated weekly, it is better to use RAG than to constantly retrain the model.
Always calculate the costs. Training a large model from scratch requires million-dollar budgets. Meanwhile, transfer learning or LoRA allows you to quickly test a hypothesis and get a great result for reasonable money.
It is worth comparing models under identical conditions. Look at response speed, cost per query, stability on complex examples, and behavior outside the training dataset. The largest model is not always the most rational choice for business.

Errors During AI Training That Reduce Accuracy
Even a correctly chosen method will not save a project if the training process is organized incorrectly. Often the problem lies specifically in the data and the evaluation method.
- Poor-quality or inconsistent annotation. If examples contain erroneous labels or annotators apply criteria differently, the model receives contradictory training signals. Clear guidelines, review of complex cases, and annotation consistency control help mitigate this risk.
- Unrepresentative data. If the dataset inadequately covers rare scenarios, varying capture conditions, user groups, or edge cases, the model may perform well on typical examples while failing in real-world conditions. Therefore, both data volume and data coverage are critical.
- Data leakage between splits. Training, validation, and test data must be separated so that the model does not gain indirect access to examples on which it is evaluated. If nearly identical images or records fall into different splits, test results may be artificially inflated.
- Inappropriate metrics. Accuracy shows the proportion of correct predictions, but it can mask issues on imbalanced datasets. If 99% of examples belong to one class, a model that always selects this class will achieve 99% accuracy, yet fail to detect rare cases. Depending on the task, precision, recall, F1-score, confusion matrix, and other metrics corresponding to real risks should be analyzed.
- Overfitting. A model can become overly tailored to training examples and lose the ability to generalize patterns. This is identified by comparing results on the training and validation splits. Regularization, data augmentation, early stopping of training, and adjustments to model complexity can help – depending on the nature of the problem.
How to Make Model Training More Effective?
High-quality training is a managed and controlled cycle:
- Establish a quality baseline before starting. Formulate core metrics and prepare test data that is as close to reality as possible.
- Audit the dataset. Clean data of duplicates, fill missing values, check inter-annotator discrepancies, and balance classes.
- Experiment systematically. Change parameters one at a time and document every step. This will help clarify which specific change yielded a quality boost versus where randomness simply took effect.
- Monitor the model post-launch. The world changes, and data ages over time. Continuous error monitoring will indicate exactly when it is time to send the model for retraining.
FAQ
How much data is needed to train an AI model?
There is no universal minimum. The data requirement depends on the complexity of the problem, the architecture of the model, the variety of examples, and the acceptable level of error. Refining a pre-trained model often requires less data than training from scratch.
How long does it take to train an AI model?
Training can take anywhere from a few minutes to a few hours for simple problems, or days to weeks for large models. The duration is affected by the amount of data, architecture, computing hardware, and number of experiments.
Which tools allow for AI training without programming?
No-code and low-code platforms allow users to upload datasets, configure training parameters, and evaluate results through a graphical user interface. However, complex projects may still require programming, data preparation, and specialized machine learning knowledge.
How do you know that a model is ready for release?
The model must meet predefined quality criteria on independent test data and perform stably in conditions close to real-world conditions. Response latency, common errors, security, and follow-up monitoring capabilities must also be assessed.